Tuesday, January 10, 2023

Baseline protein expression in 489 people!

This study might not necessarily be the most helpful to me personally, but I totally know people who will love this new resource!  


This is a clever attempt to make proteomics data more accessible to our friends in the wet labs and I wholeheartedly support that. What is the normal protein concentration distribution for a human spleen? Digging through this resource is a whole lot easier than getting a couple human spleens and digesting them and doing proteomics yourself! 

Monday, January 9, 2023

Pretend you know how to use R with MSStats Shiny!


Maybe my bar is unrealistically high since I happen to know a real bioinformatician or 3, but I saw a CV recently that was ROFLMAO (I genuinely don't know what that stands for) level inflated. It turns out that sometimes people using web based Shiny apps might think that since they can successfully load data into webpages that they are now experts in R based bioinformatics. Why not? There are definitely people out there successfully selling themselves as proteomics experts that have dropped off samples at cores or have loaded sample queues in instruments maintained by real experts. 

With all these great new web based tools you can keep the ruse going if you want and MSStatsShiny will certainly help! This tool has been live for a long time now (it feels like years and years) but now the paper is out. 


MSStats is something I've honestly never used except through the ShinyApp and I know that it is often considered the gold standard. 

The first thing I checked when I saw the paper was out was for DIA-NN compatibility, and it doesn't appear to be ready for that yet, but there is a ton that is IS ready for.


Including Proteome Discovererererererer! 

Look, I know that no one likes Discoverererer as much as I do, but as I'm training a bunch of new people this year, I keep showing them it because nothing gets us to the PSM level visualization as fast. 

Off topic, but if you were wondering what the upper limit is for PD, I can say for sure now that it can easily handle more than 2,000 single cell proteomes (250-ish SCoPE-MS runs not counting blanks/controls, etc.,). AND if you randomize your TMT channels and your injections for two closely related cell lines derived from the same type of cancer (different patients and immortalization methods) once you get north of 50 injections --  THEY CAN FIND EACH OTHER BY PCA ALONE. That might sound like not a big deal, but try that with 200 scSeq files from 2 different cell lines. PCA? Not a chance. You need real dimensionally reduction for that and cell cycle clustering and probably some level of stream-type trajectory analysis magic to find your cell type friends. I'm not sure PCA will even make sense of n<1000 per condition for scSeq. Proteomics data? BOOM. AND it gets better as you keep going (the divergent clusters are part of my experiment, don't stress it). The biggest question for me was whether I was going to break PD with 500 SCoPE-MS files. Half-way through it ain't even really struggling, so I like my chances. 

(If you are stupid enough to try processing 4,000 single cell proteomes in a desktop interface I strongly encourage you to turn off "Found in Samples" and "Abundances" in your PSM and Peptide Group level reports. I still strongly recommend leaving the Data Distributions post-processing node in. It is just too useful, but hide the results when looking at your full reports because it wills struggle with a matrics with 4,000 proteins X 4,000 conditions. (Imagine what that is at the PSM level. Even though it isn't maxing out my RAM something is limiting the speed at which I can sort through the data). 

Pretty sure I need to run MSStatsShiny locally for this analysis, but I might try the web interface anyway. 

Sunday, January 8, 2023

SyntheDIA -- Simulate your sample for experiment optimization!


Yo, you know what ain't getting cheaper? Instruments and instrument time! You'd think with all the competition out there now, we'll soon see vendors competing with pricing, and I bet we will soon. (For real, we should share pricing information, somebody put up a post on Reddit where you can put your quote information in).

One way you could save time and maybe a lot of money is not running optimization experiments for new samples (or for getting to the proteins you actually care about).

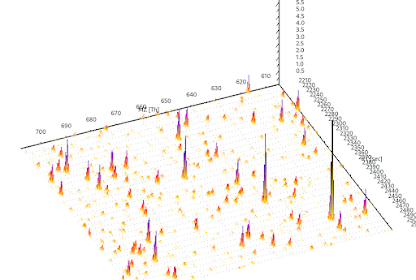
That's what SyntheDIA is! 
You can read about it here. 


Or you can check it out (along with some disclaimers that I didn't find immediately apparent in the paper itself) at https://synthedia.org/

If you just type it into a search engine you'll find that most of them think you are terrible at typing and you mean to swap the D to an S. 
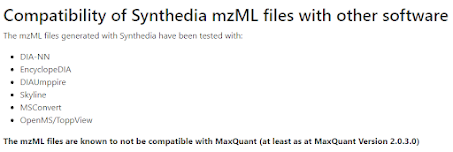

The web interface can directly do some SyntheDIAing for you, but if you want to do more than a couple of files you can install it locally. The authors are also open to collaborating (which is a really smart thing to have listed on a cool resource). 
Thursday, January 5, 2023

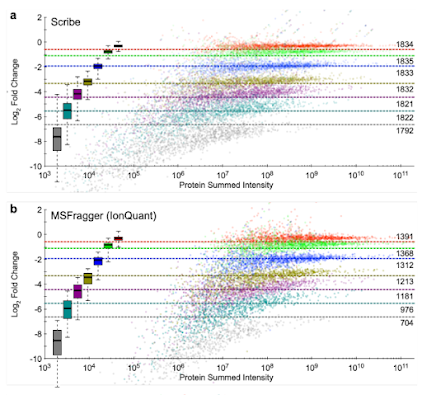
Use super fancy DIA approaches for DDA with Scribe!


You know how we went from 
"DIA is cool, but WTF do we do with all of these crappy noisy spectra??" 
to
"We have 14 tools that do amazing neural learning machine stuff that we trust so much that we won't even look at these crappy noisy spectra anymore, they're probably okay cause this machine told us it was" 

(That was a fun ABRF core director meeting when everyone was like....ummmm....what....guess this is what we do now...???)

That stuff is probably all now very well validated, or if it isn't, it will be very hard to find anyone to blame for it now. Point of fact, though, deep learning intelligence thingies are much much better now. You can even make them write code for you! 

What if you applied this knowledge to D D A data? Well, that's what Scribe is! 


Wednesday, January 4, 2023

MS Imaging -- Awesome webinar Monday 1/9/2023


Hey you! Are you considering buying the expensive mass spec that makes the pretty pictures? Want to find out what it can actually do (beyond making pretty pictures!)

Sign up for this webinar on Monday! 

Details are here!

Tuesday, January 3, 2023

Publication ready spectra with mirror plots -- you'll want to USE this!


...and the winner for the hardest tool to find when using basically any internet search engine...USE

Universal

Spectrum

Explorer

I've been looking for this thing for over a year! 

You can use USE here: https://www.proteomicsdb.org/use

You can get the code to use USE locally here! https://github.com/kusterlab/universal_spectrum_explorer

You can read about it here! 

Think it looks like the amazing IPSA that you're already USEing? It ought to, it is an expansion on that great resource! 


Monday, January 2, 2023

Use proteomics technology around the home!


Happy New Year! 

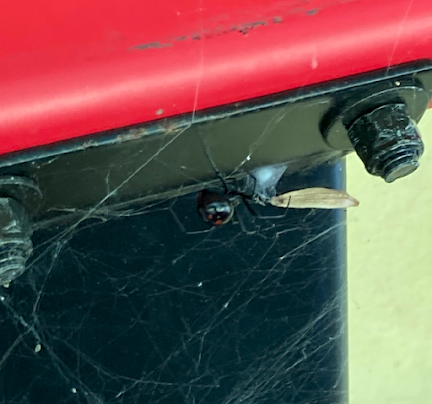
I'm going to kick off 2023 by showing you my LEAST FAVORITE PHOTO OF 2022. This is a picture of an attachment on some excercise equipment that I have outside under my deck. This pretty lady and her bag of eggs were right by my face for a minute before I zoomed in on this picture and she had an unfortunate accident while I tried to carefully rehome her with an old aluminum baseball bat. 

Pug Mountain Vineyards is a spider friendly establishment but Latrodectus isn't a spider you mess around with when you have a 1 year old running around.  Fortunately, these spiders are well known to use ballooning to disseminate. They don't cluster in large populations. Any of her eggs that survived a very thorough removal process by myself and by a well compensated professional who came out twice would have only produced small spiders that would have moved on to nicer places THAN UNDER MY DECK. 

Obviously a small spider that I found on an uncharacteristically warm day right before the holidays that looked sort of like her would just be coincidental appearances. I've got bifocals and spiders are small. Just in case a tiny amount of it that remained from the unfortunate accident that befell that little organism, clearly wouldn't S-Trap out and show any Latrodec...tus....hesperus....
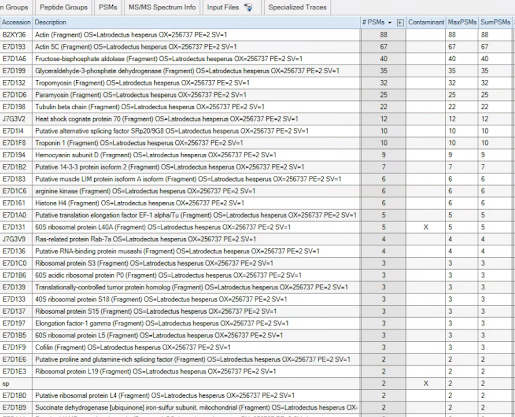
...so...I think I'm moving....but, hey! who said you couldn't come up with a practical application for proteomics! 
Thursday, December 29, 2022

Aptamers, capillary electrophoresis, or MS/MS?


You CAN have it all, as proven in this study that is so new it is published in 2023! 

What this group shows is that well designed aptamers (DNA things that are designed to enrich other things -- legitimately you can enrich everything from environmental pollutants through proteins) they can enrich and almost directly analyze what they enriched! 

Why?!?!

You've got me. Actually, I think that most aptamer assays use fluorescence so MS/MS on the back end. MS/MS would allow you to QC that aptamer to see if it really is grabbing what you want it to. In the example they show it looks like their aptamer grabs a couple of things and by MS/MS signal they can work out the ratios of those things. Having an integrated system for QC'ing aptamers or doing quantification on enriched molecules from multi-purpose aptamers sounds a lot easier than digesting each aptamer individually, so this seems like a smart/weird application. 

The MS instrument used was a TripleTOF 4600. 

Tuesday, December 27, 2022

MS-DAP -- Another powerful data interface for proteomics!


Well....you know....sometimes science is so awesome that if you have to pull a couple all-nighters in the lab during the holidays it is SO SO WORTH IT. And sometimes it just makes you wonder if it would be more fun making a lot more money running a backhoe. My kid would definitely think I was cooler if I ran a backhoe -- when in doubt, get him another toy ashpalt roller -- and I did get to operate one and it was sort of awesome. 

HEY! I haven't read a paper in like 2 weeks, except for the ones I'm reviewing and I can't talk about those yet. And this one has been in the queue! 
Wow. That title is super long. At first glance I assumed I was a coauthor on this. Still worth it.

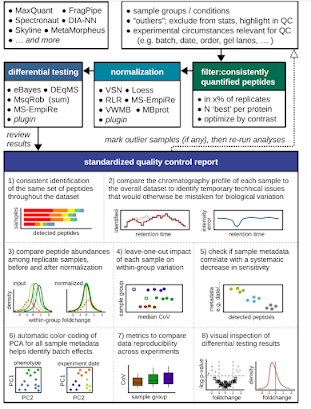
Look, there are a bunch of ways now to QC your proteomics data and to process it.

For anyone dreaming of a free interface for DIA-NN data (!!!!!) you're in business! 

Now, MS-DAP isn't as easy as something like LFQ-Analyst (which dropped a new version at HUPO that accepts FragPipe data! which, I guess if you run DIA-NN through FragPipe, you're probably good to go!) but the instructions are super clear and you can set this all up locally after you follow all the friendly instructions! 


Monday, December 19, 2022

The ProteomicsShow holiday special pilot episode, featuring Dr. Lindsay Pino!


We planned a surprise that dropped yesterday, but I was at a family party and forgot to announce it. 

Background: Ben and I recorded some stuff before tricking US HUPO into backing THE Proteomics Show, so we released the very first thing we recorded -- an hour long chat with Dr. Lindsay Pino. 

The downside of talking with Lindsay for an hour is how uncool you feel afterward. 

You can share this feeling of uncoolness by finding the episode wherever you get podcast things!